September 2026 AI Model Rankings: Reading the Chart
The September 2026 AI model rankings below reproduce a chart credited to Uncle Cat Next Door. It places Claude Opus 5.5 first, followed by Claude Fable 5.1, GPT-6 Astra, and GPT-6 Sol. Those are the chart’s positions, not results of a benchmark I ran.
The material published with this article does not provide scores, test conditions, weights, or a reproducible calculation. Treat the list as a dated tier chart for discussion, not evidence that one model will outperform another on your workload.
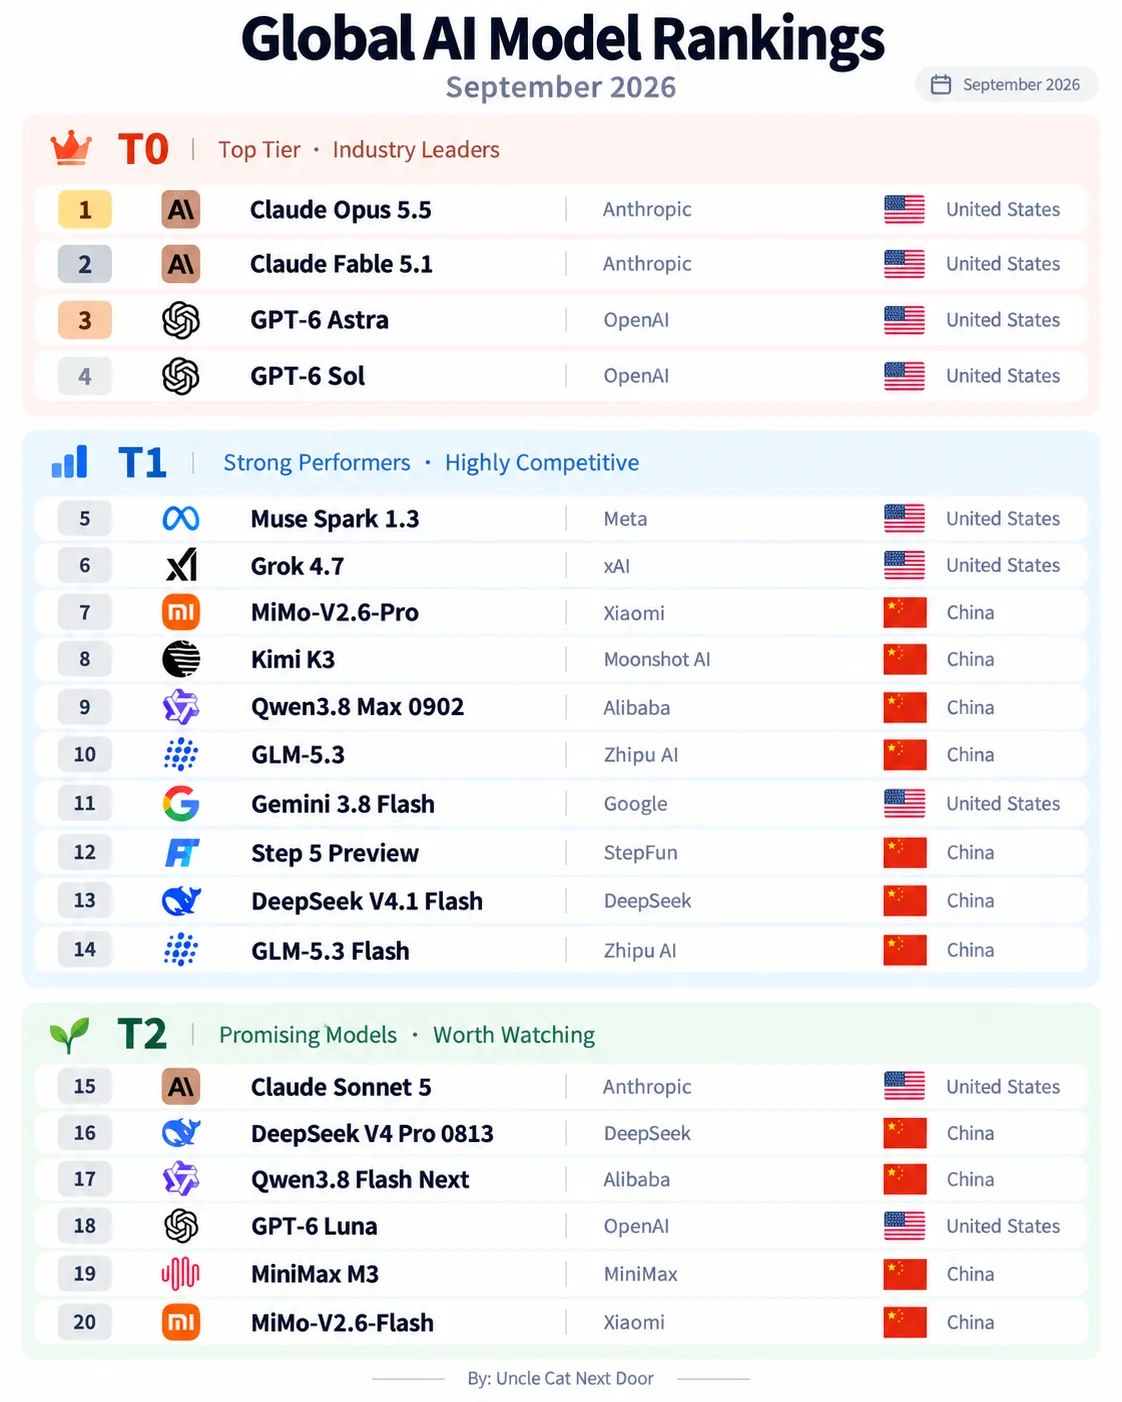
Chart credit: Uncle Cat Next Door. The original source URL and ranking methodology were not supplied with the chart.
What this chart does and does not establish
The chart records names, developers, countries, positions, and three tiers: T0, T1, and T2. It does not show the measurements that produced the order or define numerical boundaries between tiers.
My earlier version described the order as a composite of public benchmarks, developer evaluations, coding suites, and deployment economics. I did not publish evidence for that calculation. I have removed that claim, along with unsupported explanations of launch dates, prices, and why a model supposedly earned its position.
The model names and tier assignments in the table are transcribed from the chart. Their inclusion is not independent confirmation of product availability or official naming. This is a September snapshot, not a live leaderboard.
The 20 positions reported in the September chart
| Chart position | Model label in chart | Developer | Chart tier |
|---|---|---|---|
| 1 | Claude Opus 5.5 | Anthropic | T0 |
| 2 | Claude Fable 5.1 | Anthropic | T0 |
| 3 | GPT-6 Astra | OpenAI | T0 |
| 4 | GPT-6 Sol | OpenAI | T0 |
| 5 | Muse Spark 1.3 | Meta | T1 |
| 6 | Grok 4.7 | xAI | T1 |
| 7 | MiMo-V2.6-Pro | Xiaomi | T1 |
| 8 | Kimi K3 | Moonshot AI | T1 |
| 9 | Qwen3.8 Max 0902 | Alibaba | T1 |
| 10 | GLM-5.3 | Zhipu AI | T1 |
| 11 | Gemini 3.8 Flash | T1 | |
| 12 | Step 5 Preview | StepFun | T1 |
| 13 | DeepSeek V4.1 Flash | DeepSeek | T1 |
| 14 | GLM-5.3 Flash | Zhipu AI | T1 |
| 15 | Claude Sonnet 5 | Anthropic | T2 |
| 16 | DeepSeek V4 Pro 0813 | DeepSeek | T2 |
| 17 | Qwen3.8 Flash Next | Alibaba | T2 |
| 18 | GPT-6 Luna | OpenAI | T2 |
| 19 | MiniMax M3 | MiniMax | T2 |
| 20 | MiMo-V2.6-Flash | Xiaomi | T2 |
What a reproducible model ranking would need
An exact position needs more than a model label. To evaluate the order, I would want:
- named tasks and their source, including whether the model could have seen them before;
- exact model versions, reasoning effort, tools, prompts, and context limits;
- scores, repeated runs, missing results, and a rule for handling failures;
- a collection date and the weights used to combine different measures;
- separate reporting of correctness, time, and cost before reducing them to a single number.
Without those details, position 1 versus position 2 does not tell us the size or reliability of a performance difference. Even a well-documented benchmark can rank models differently from a particular team’s work.
For a comparison with visible conditions, my Claude Opus 5 versus Claude Fable 5 test publishes eight tasks, scoring rules, and its one-run limitation. It covers earlier model versions and cannot validate this September chart.
How to choose a model using stronger evidence
Use the chart to identify questions, then test the models available to you on work you can check. My custom LLM evaluation guide explains how to keep hidden tests, blind review, and variance visible. The AI workflows guide connects those results to task boundaries and verification.
For a worked example with dated public data, the GPT-5.6 Sol, Terra, and Luna comparison separates repeated-task coverage from latest-run time and cost. It is another historical snapshot, not a substitute for testing a newer generation.
Choose by verified results under your constraints. Until the chart’s original source and method are available, its exact ordering should not decide a purchase or a production model choice.